


On December 15, 2025, NVIDIA quietly made one of the most consequential open-source AI releases in the industry’s history.
Nemotron 3 Nano isn’t just another open-weights model competing with Llama or Mistral. It’s a complete AI development stack: the model weights, the training data, the post-training recipes, the reinforcement learning environments—everything you’d need to reproduce or customize the model from scratch. No major AI lab has ever released this much.
For enterprises evaluating whether to build or buy their AI capabilities, this changes the calculus entirely.
I’ve spent the last two decades building and scaling hardware-intensive businesses. When I co-founded Deco Lighting in 2005, we grew it from a startup to over $50 million in revenue by understanding one thing deeply: the economics of infrastructure at scale. Whether it’s LED manufacturing or AI inference, the math is the same—fixed costs, variable costs, break-even thresholds. And what NVIDIA just released fundamentally reshapes that math for enterprise AI.
The Business Case: 97% Cost Reduction at Scale
Let’s start with what matters most to the CFO.
Consider a mid-sized enterprise processing 500,000 AI inference requests daily—think customer service automation, document analysis, or code assistance. Using commercial API providers at roughly $0.09 per request, that’s about $1.35 million per month.
Self-hosting Nemotron 3 Nano on four H200 GPUs—including hardware amortization, operating costs, and staffing—runs approximately $28,000 monthly. That’s a 97% reduction. Even at 100,000 daily requests, the economics still favor self-hosting by 95%+.
This is the same pattern I saw in LED lighting. Early adopters paid premium prices for the convenience of turnkey solutions. But once we understood the manufacturing economics—and could deliver at scale—the value equation flipped entirely. The enterprises that built internal capabilities captured that margin themselves.
The reason Nemotron’s economics work: it delivers the intelligence of a 30-billion-parameter model while only computing with 3 billion parameters per request. It’s like having a team of 30 specialists but only paying for the 3 you actually need for each task.
How It Works: A Technical Primer for Non-Engineers
My background is electrical engineering—I spent time in Professor Fainman’s ultrafast nanoscale optics lab at UC San Diego working on silicon photonics and micro-ring resonators. That training taught me to break down complex systems into their fundamental building blocks. Let me do that here.
Nemotron 3 combines three innovations that together achieve breakthrough efficiency.
Innovation #1: The Hybrid Architecture
Traditional AI models use “attention”—a mechanism that re-reads every previous word before generating the next one. Double the document length, quadruple the compute cost. This is why processing long documents gets expensive fast.
Nemotron 3 takes a hybrid approach, interleaving two types of layers:
Mamba layers (23 of them): These are efficient “note-takers” that track themes across massive documents using compressed states rather than storing everything explicitly. Think of a skilled executive assistant who captures the essence of a 100-page report without photocopying every page.
Attention layers (just 6): These are the “detail specialists” who catch exact syntax, logical relationships, and precise reasoning when needed.
By limiting expensive attention to just 6 strategic layers instead of 52, NVIDIA achieves 4x faster inference than their previous generation—without sacrificing accuracy.
Innovation #2: Mixture of Experts (MoE)
The model contains 128 specialized “expert” networks plus 2 generalists. But here’s the key: for any given request, only 6 relevant experts activate—chosen by a learned “router” that matches the task to the right specialists.
Total parameters: 31.6 billion. Active parameters per request: just 3.6 billion.
This is analogous to how we structured teams at Deco. You don’t need every engineer on every project—you need the right specialists for each challenge, with a few generalists who can bridge domains. The MoE architecture operationalizes this principle at the neural network level.
Innovation #3: What’s Coming in 2026
NVIDIA has announced Nemotron 3 Super (~100B parameters) and Ultra (~500B parameters) for H1 2026, introducing additional innovations:
Latent MoE: Compresses tokens before routing, enabling 4x more experts at the same compute cost. NVIDIA’s analogy: “Chefs sharing one big kitchen but each keeping their own spice rack.”
Multi-Token Prediction: The model predicts multiple future tokens simultaneously, then verifies in parallel. This achieves ~1.8x speedup with 80-90% draft acceptance rates.
NVFP4 Quantization: Training directly in 4-bit precision on Blackwell GPUs, reducing memory 4x while maintaining accuracy. NVIDIA reports 7x speedup in matrix operations versus the previous generation.
The Benchmarks: Where Nemotron Wins (and Doesn’t)
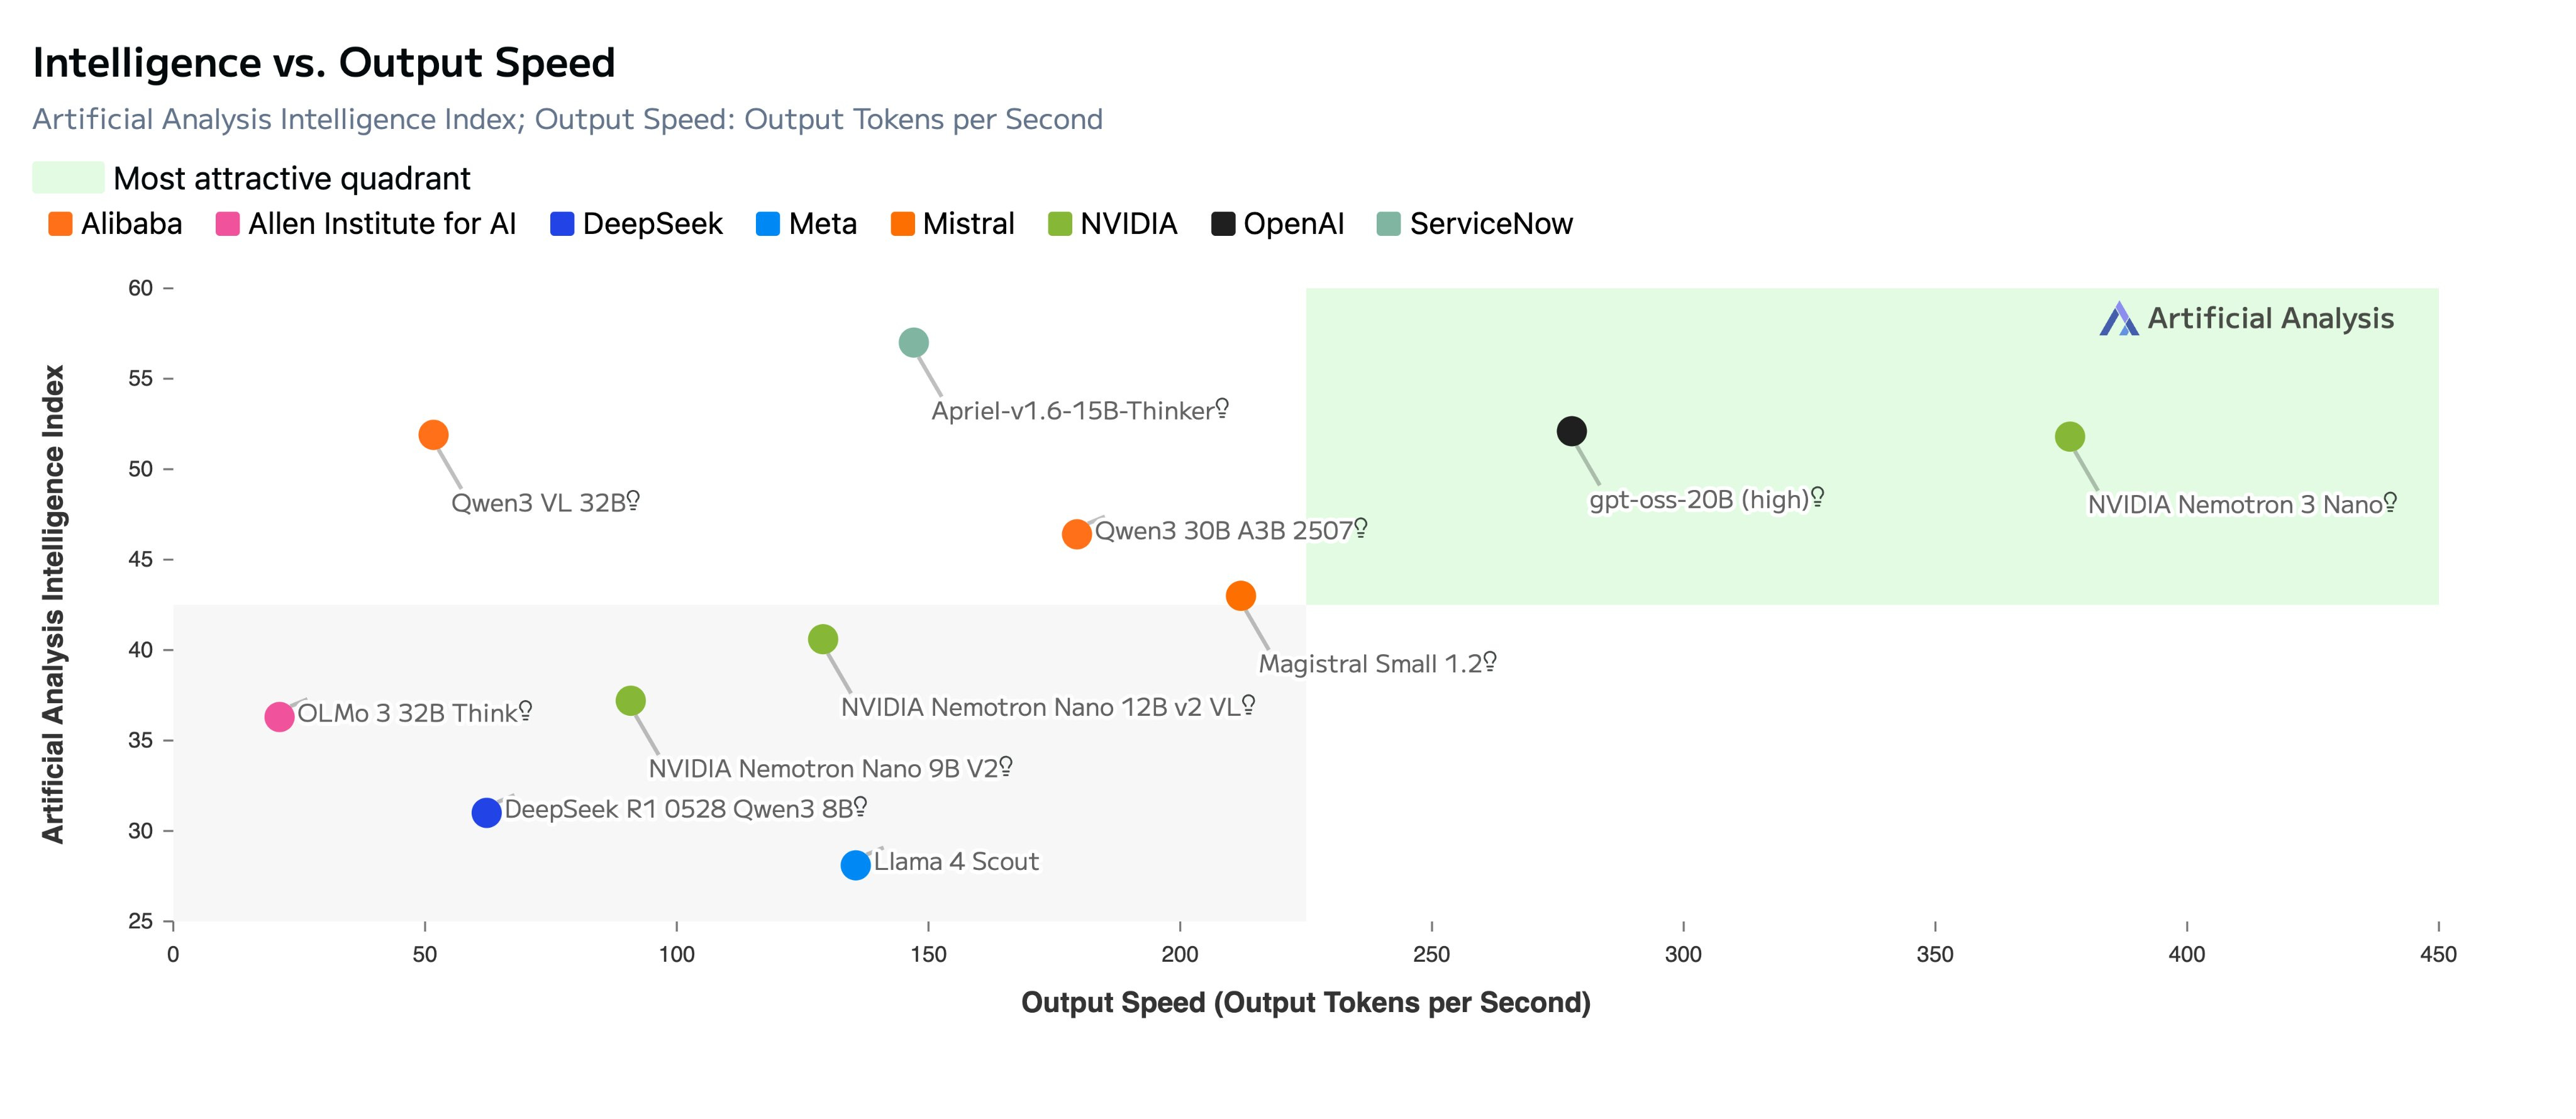
Nemotron 3 Nano shows a distinctive performance profile—optimized for enterprise agentic workloads rather than pure reasoning benchmarks.
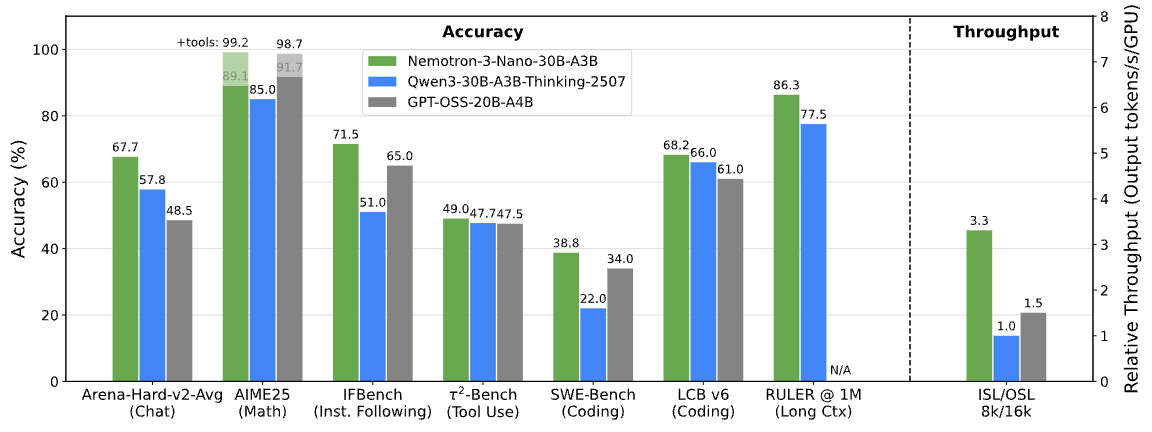
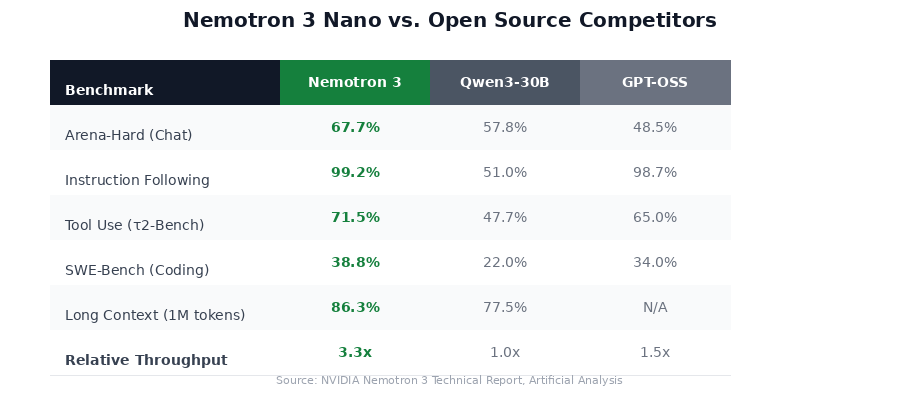
The 99.2% instruction-following score stands out—critical for enterprise agentic systems where models must reliably execute multi-step workflows. The 3.3x throughput advantage translates directly to infrastructure savings at scale.
Where Nemotron trails (competitive coding on LiveCodeBench, some multilingual tasks), the gaps reflect different training priorities rather than fundamental limitations.
The Openness Gap: What NVIDIA Is Actually Releasing
Here’s where Nemotron 3 fundamentally differs from other “open” models.
Meta’s Llama releases weights but withholds training data—roughly 15 trillion tokens, completely unavailable. Mistral takes the same approach. DeepSeek publishes detailed methodology papers but not datasets.
NVIDIA is releasing:
~3 trillion tokens of pretraining data including Nemotron-CC-v2.1 (2.5T English tokens from Common Crawl), code datasets, and math corpora
13 million post-training samples—described as 2.5x larger than any previously available post-training dataset
Complete training recipes for supervised fine-tuning, reinforcement learning from verifiable rewards, and RLHF
NeMo Gym with 10+ RL training environments covering coding, math, tool use, and multi-turn conversations
11,000 agentic safety traces for evaluating and mitigating risks in tool-using workflows
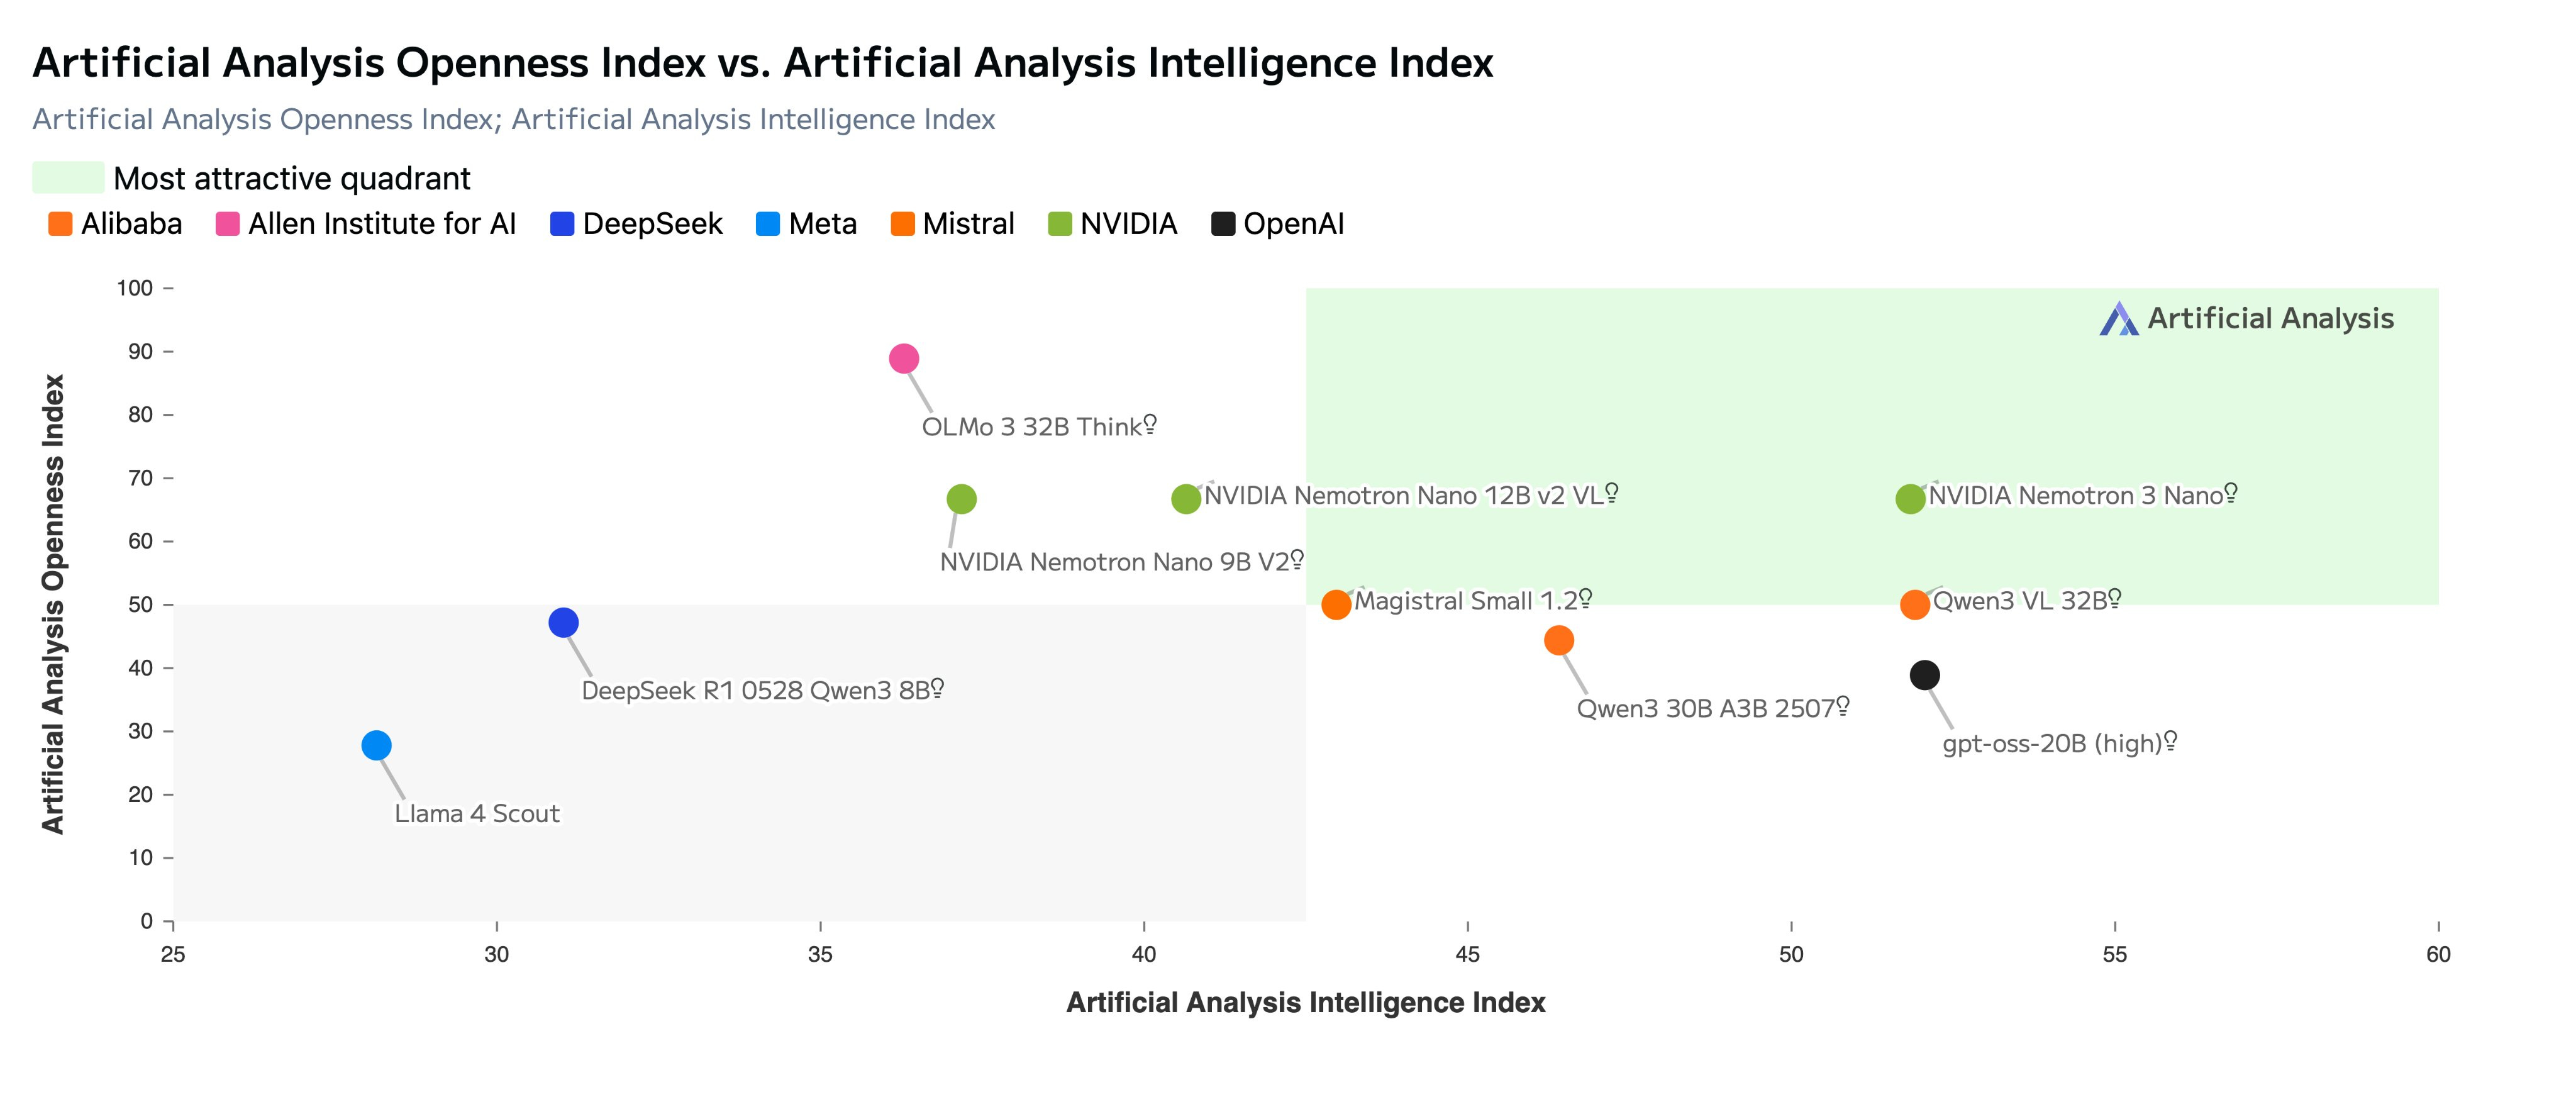
The NVIDIA Open Model License permits commercial use without revenue thresholds or monthly-active-user limits (unlike Llama’s 700M MAU restriction). For enterprises requiring reproducibility and auditability, this transparency is unprecedented.
Having built a manufacturing business, I can tell you: this level of transparency is what separates vendors from partners. When a supplier shows you their bill of materials, their process specs, their quality controls—that’s when you can build a real long-term relationship. NVIDIA is doing that here with AI.
The SaaS Reckoning: Who’s at Risk
Here’s what keeps me up at night as an investor: what happens to software companies whose “AI moat” is essentially a wrapper around proprietary APIs?
For the past two years, enterprise software companies have raced to bolt AI features onto their platforms. Salesforce added Einstein GPT. ServiceNow launched Now Assist. Workday rolled out AI assistants. Zendesk, Freshworks, HubSpot—everyone shipped an “AI copilot.”
The pitch to customers: “Pay us $50-150 per seat per month, and we’ll handle the AI complexity for you.”
The pitch to investors: “AI features increase stickiness and justify premium pricing.”
But here’s the problem. Most of these AI features are thin wrappers around OpenAI or Anthropic APIs. The differentiation isn’t in the model—it’s in the integration, the UX, the workflow automation. That’s real value. But it’s not $100/seat/month of value when the underlying inference costs are collapsing.
Let me put concrete numbers on this:
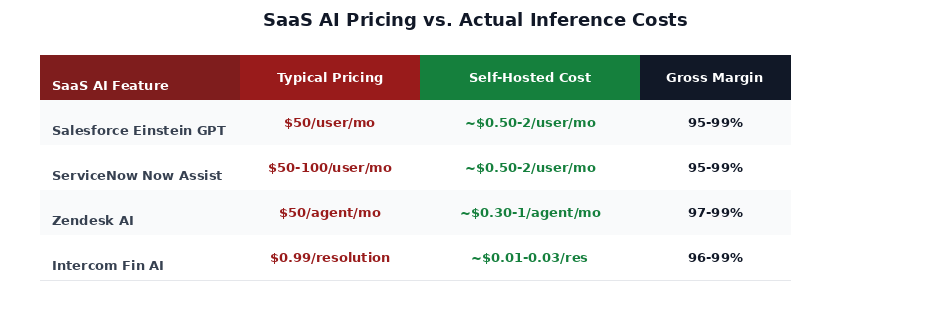
These margins look fantastic—until your enterprise customers figure out they can replicate 80% of the functionality with Nemotron + a competent platform team for 1/50th the cost.
And that’s exactly what Nemotron enables. A 10,000-seat enterprise paying ServiceNow $500K-1M annually for AI features can now self-host equivalent capabilities for under $30K/year in compute—and own the data, customize the model, and eliminate vendor lock-in.
The “AI Wrapper” Warning Signs
As an investor, I’m now scrutinizing every SaaS company’s AI strategy through this lens:
Is the AI a feature or the product? Companies where AI is bolted onto existing workflows (most enterprise SaaS) are vulnerable. Companies where AI is the core product with proprietary training data (like Bloomberg Terminal’s AI) have more defensible positions.
What’s the actual model differentiation? If the answer is “we use GPT-4 with custom prompts and RAG,” that’s a thin moat. If it’s “we’ve fine-tuned on 10 years of proprietary customer interaction data that no one else has,” that’s different.
Can the AI pricing survive transparency? When customers understand that AI inference costs $0.001-0.01 per interaction, will they keep paying $1-5? The SaaS companies that can’t justify their pricing with genuine value-add will face margin compression or churn.
Does the company have workflow lock-in beyond AI? Salesforce owns your CRM data and processes. ServiceNow owns your IT workflows. That lock-in is real—but it’s separate from AI value. The risk is customers saying “I’ll keep your platform but skip your AI add-on.”
Who’s Most Exposed
The companies I’d be most cautious about:
Customer service AI platforms (Zendesk AI, Freshdesk Freddy, Intercom Fin): These are essentially GPT wrappers with CRM integration. The core product—ticketing, routing, analytics—remains valuable, but the AI premium is vulnerable. When Nemotron can handle 99.2% of instruction-following tasks at 3.3x the speed, the “we’ll handle AI complexity” pitch weakens considerably.
Horizontal AI copilot add-ons: Any SaaS company charging $30-50/seat/month for “AI assistant” features that are primarily summarization, drafting, and Q&A. These use cases are now commodity.
AI-native startups without proprietary data: The wave of 2023-2024 startups built entirely on GPT-4 APIs with “better UX” as the differentiator. Many raised at 50-100x ARR multiples on the assumption that AI complexity was a barrier. That barrier just collapsed.
Who Might Be Insulated
Not everyone is equally exposed:
Vertical SaaS with domain-specific training data: Companies like Veeva (life sciences), Procore (construction), or Toast (restaurants) have years of industry-specific data that generic models can’t match. Their AI features—when built on proprietary fine-tuning—have genuine differentiation.
Infrastructure-layer platforms: Companies that provide the plumbing for AI deployment rather than the AI itself. Databricks, Snowflake’s Cortex, and similar platforms benefit regardless of which model customers choose.
High-compliance, high-trust verticals: Healthcare, legal, and financial services companies where the “AI wrapper” includes regulatory compliance, audit trails, and liability frameworks. The model is commodity; the compliance infrastructure is not.
The Investor Takeaway
I’m not saying enterprise SaaS is dead—far from it. Workflow automation, data management, and platform lock-in remain powerful moats. But the “AI premium” that many companies have baked into their pricing and valuation needs to be re-examined.
When I was building Deco, we watched LED commoditization happen in real-time. Early movers charged premium prices for “integrated solutions.” Within five years, the underlying technology became commodity, and the winners were companies with genuine differentiation in design, distribution, or customer relationships—not just “we were early to LEDs.”
The same pattern is playing out in AI, just faster. Nemotron 3 isn’t the cause—it’s the accelerant. The question for every SaaS investment is: when AI inference costs approach zero, what’s actually left?
When to Consider Nemotron 3 for Your Enterprise
Nemotron 3 Nano warrants serious consideration when:
Data sovereignty requirements mandate on-premise deployment (regulated industries, government, defense)
Volume exceeds break-even thresholds where API costs dwarf infrastructure investment (typically 50,000+ daily requests)
Agentic architectures require many concurrent lightweight agents with tool-calling capabilities
Long-context applications need to process entire codebases, compliance documents, or multi-hour conversation histories
Customization needs demand fine-tuning on proprietary data without vendor dependencies
Early enterprise adopters include Accenture, ServiceNow, Perplexity, Deloitte, EY, CrowdStrike, Palantir, Siemens, and Zoom—spanning consulting, cybersecurity, developer tools, and communications.
The Strategic Picture: NVIDIA’s Full-Stack Play
This release reflects NVIDIA’s ambition to control the AI value chain from silicon through software to models. By releasing complete training infrastructure rather than just weights, NVIDIA creates ecosystem dependency—developers building on NeMo Gym and NeMo RL become natural customers for NVIDIA hardware optimizations.
The model deploys via NVIDIA NIM microservices with under-five-minute setup, supporting vLLM for high-throughput batching, SGLang for multi-agent tool-calling, and TensorRT-LLM for latency-critical applications.
As multi-agent AI systems become the architecture of choice for enterprise automation, the model optimized specifically for that workload—available with unprecedented openness—represents a meaningful strategic option for companies building serious AI infrastructure.
For those of us who’ve spent careers at the intersection of hardware economics and business scaling, this is the moment enterprise AI gets real. The tools are open. The math works. The question is no longer whether to build AI capabilities internally—it’s how fast you can move.
About the Author
Ben Pouladian is a tech investor and AI infrastructure analyst based in Los Angeles. He brings a unique perspective to semiconductor analysis through his electrical engineering background from UC San Diego (2004), where he worked in Professor Yeshaiahu Fainman’s Ultrafast and Nanoscale Optics group studying micro-ring resonators and silicon photonics. Ben co-founded Deco Lighting in 2005, which he grew into a national LED lighting manufacturer before transitioning to focus on technology investing. He currently serves as CEO of BEP Holdings and Chairman of the Terasaki Institute Leadership Board. Follow his research at benpouladian.com and on Twitter @benitoz.
Resources
NVIDIA Nemotron 3 Research Page
Nemotron 3 Nano on Hugging Face
Nemotron 3 Nano is available now through inference providers including Baseten, DeepInfra, Fireworks, FriendliAI, OpenRouter, and Together AI. AWS Bedrock availability is forthcoming.
Coming back to this because the Super just dropped and it validates everything you wrote about the enterprise economics angle. The Nano was the opening move; Super takes it further with 120B total parameters, 12B active, and the same hybrid Mamba-Transformer MoE architecture but at a scale that competes with frontier models on reasoning.
The LatentMoE routing in Super is the bit that wasn't obvious from the Nano release. It compresses tokens before routing across 512 experts, which is how they pack in 4x more expert capacity at the same compute cost. I went deep on the full architecture here https://reading.sh/inside-the-model-merging-three-ai-architectures-into-one-c5dcc7302528 because the engineering choices are genuinely different from anything else in the open-source space.
Synthetic already picked up Super for their flash tier. A 120B model at flash speeds. The enterprise cost calculus you outlined in this piece just got even more interesting.
Outstanding analysis on the SaaS wrapper risk. The part about break-even thresholds matches what we saw deploying on-prem inference last year, costs dropped like 95% once we hit volume. I dunno if enough VCs are factoring this commoditization into their valuations tho, theres gonna be a reckoning for companies charging $100/seat for glorified API calls.